How Law Firms Can Optimize for AI Search and LLM Visibility

AI search works differently from traditional search, and it’s already reshaping how prospects find legal help.
Instead of scanning organic results, tools like Google’s AI Overview and ChatGPT provide prospects with direct answers.
AI summaries reduce the need to click through for some informational searches. And that makes it harder to get exposure for your service offerings, even if you already have high SEO rankings.
Question-style searches, which are how legal problems often get typed into a search bar, trigger Google’s AI Overviews 57.9% of the time, according to Ahrefs’ analysis of 146 million search results.
And when an AI summary appears, click-through to a traditional website drops from 15% to 8%, according to Pew Research.
This guide covers what that shift means for law firm marketing, and the specific steps to stay visible as AI systems increasingly decide who gets found.
Understanding AI Crawlers
AI crawlers are automated programs that visit a website and read its content, much like how Google has always indexed the web.
However, not all AI crawlers serve the same purpose.
Training a Model vs. Answering a Question
There are two main types of AI crawlers relevant to digital marketing: training crawlers and retrieval crawlers.
Training crawlers collect content to help build or refine an AI model over time. Search retrieval crawlers, on the other hand, build the index AI assistants use to answer questions directly in live sessions.
Training crawler access is separate from live retrieval and does not by itself make a page eligible for citation. On the other hand, allowing a search crawler does, since that’s the one actually feeding live answers.
To draw a clearer line between training crawlers and retrieval crawlers, let’s explore what OpenAI uses:
- GPTBot: Collects content for training and improving OpenAI’s models.
- OAI-SearchBot: Powers ChatGPT’s live search results and can cite a website with a backlink.
| GPTBot | OAI-SearchBot | |
| Main purpose | Model training | Indexing for ChatGPT live search results |
| Citations and links | None | Can cite a page with source links |
| When allowed | Your content may be used to train future models | Pages eligible to appear in ChatGPT responses |
| Common setup | Block | Allow |
Here’s a tip: A firm can allow one and block the other.
Allowing OAI-SearchBot while blocking GPTBot is a common setup, staying eligible to be cited in a live ChatGPT answer while opting out of training.
Take note that a third OpenAI agent, called “ChatGPT-User,” doesn’t automatically crawl and will only fire when a person specifically requests ChatGPT to fetch content from a specific page. These user-triggered crawlers are also beneficial for your visibility in AI conversations through source links on pages that the user requested to fetch.
What About Google AI Overviews and Gemini?
Google works a bit differently and has been a central point of confusion for a lot of firms.
For starters, Google-Extended is a ‘robots.txt’ control (not a standalone crawler) used for Gemini training and grounding purposes, as well as governing whether content has already been crawled. In addition, blocking it prevents Google from using your website content (e.g., images, text, and data) to train future Gemini and Vertex AI models, without affecting your organic search engine rankings.
As for AI Overviews, Google simply pulls from the same search index that Googlebot already built. That means that if you enable Googlebot access for the sake of your organic search eligibility, you also enable indexation for AI Overviews by default (although inclusion is not guaranteed).
| Googlebot | Google-Extended | |
| Main purpose | Indexing for Google search and AI Overviews | Controls whether content can be used for Gemini training |
| Citations and links | Links on Search Engine Results Pages (SERPs) and source links in AI Overviews | No direct links or citations tied to this control |
| When allowed | Pages maintain visibility in search results and AI Overviews | Allows Google to use content for Gemini training |
| Common setup | Allow | Depending on firm’s training preference |
Crawler access is only half the picture, though:
Why Allowing a Crawler Doesn’t Guarantee Citation or Visibility
Letting a crawler in only makes a page eligible to be considered. It doesn’t automatically mean the page will be used and cited as an information source.
Certain characteristics make content easier for AI systems to retrieve, understand, and cite, such as including clear and direct answers to exact user questions. A crawled page that’s thin or vague can still get skipped.
Making Your Law Firm Website Easier for AI Search to Understand
According to Google’s guidance on AI features, a site doesn’t need special schema or AI-specific files to appear in AI Overviews or AI Mode.
A page simply needs to be indexed and eligible to show with a snippet, same as regular search.
The real work here is clarity and making sure pages are easier to read, trust, and quote for crawlers.
1. Lead With the Answer, Then Organize by Client Intent
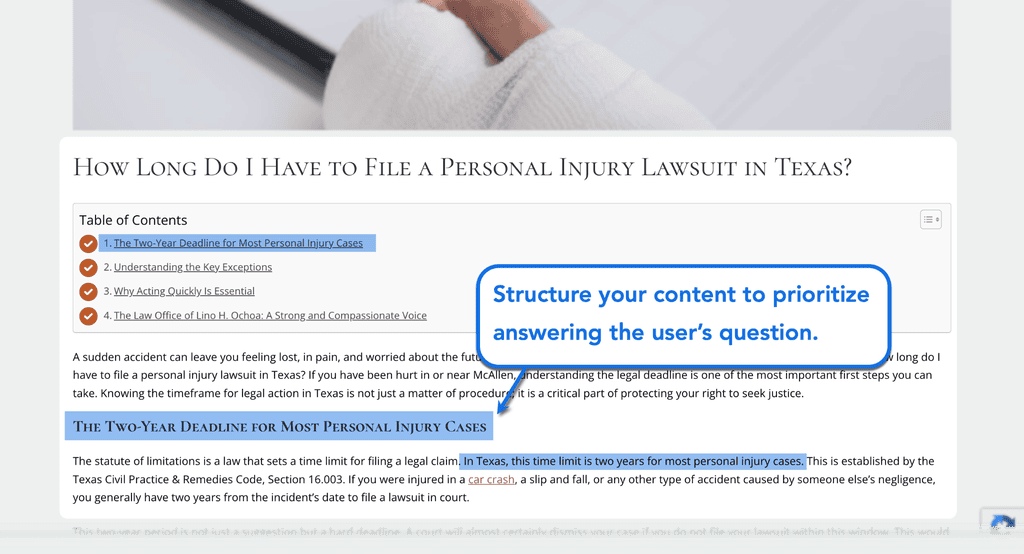
Content that front-loads the direct answer in the first sentence or paragraph makes it easier for both users and AI systems to extract information.
Someone asking “how long do I have to file a personal injury claim in Texas?” shouldn’t have to scroll through several blocks of text to find the information they need.
Also prioritize building pages around specific problems, not broad topics.
A page on “Can I keep my car if I file Chapter 7 bankruptcy?” for instance, usually matches how people phrase a question better than a single, catch-all “bankruptcy” page.
Some additional tips to make your page easier to quote and cite for crawlers:
- Write the question as a heading or subheading
- Visible “hints” on the answer (i.e., the answer as another subheading)
- Mention the jurisdiction and a review date
- Accurate, up-to-date details and sources below
2. Keep Details Consistent and Linked
As a rule of thumb, use the same firm name, attorney names, practice area labels, contact details, and office information across your entire digital footprint. Mismatches (e.g., old office address, outdated phone number, or misspelled attorney name) may be enough inconsistency to confuse indexing tools.
Take note that this covers your presence outside your website, like legal directory listings and bar association profiles.
In addition to consistent details, link relevant practice pages, attorney bios, case results, and supporting articles to each other. This helps your content be more findable to both human readers and crawlers.
3. Keep Important Content in Plain HTML
Googlebot renders JavaScript, but other AI crawlers don’t, like OAI-SearchBot, GPTBot, ClaudeBot, and PerplexityBot.
For most websites (not just in the legal industry), JavaScript is used for content inside tabs, carousels, modals, accordions, or other dynamic elements loaded in by your page builder. These script-dependent content may be harder for some crawlers to access reliably.
A quick way to check:
- View the page source (not the ‘Inspect’ option) on Chrome
- Search for a sentence from the main content
- If it’s missing, it may be loading through a script
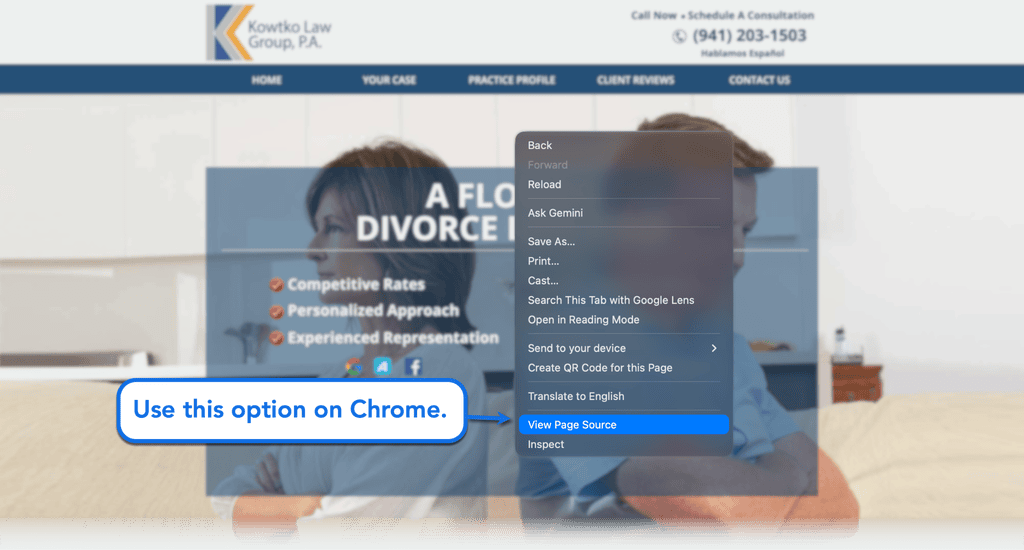
Just remember that the steps above are just for initial diagnosis. The definitive way to check for hidden, script-based content is through rendered HTML or crawler testing.
4. Show Who Wrote Content and When It Changed
Readable is one thing. Trustworthy is another.
Improve content trustworthiness by crediting attorneys for the legal content on your website. Link to detailed attorney bios that list credentials, bar admissions, educational background, and other noteworthy accomplishments.
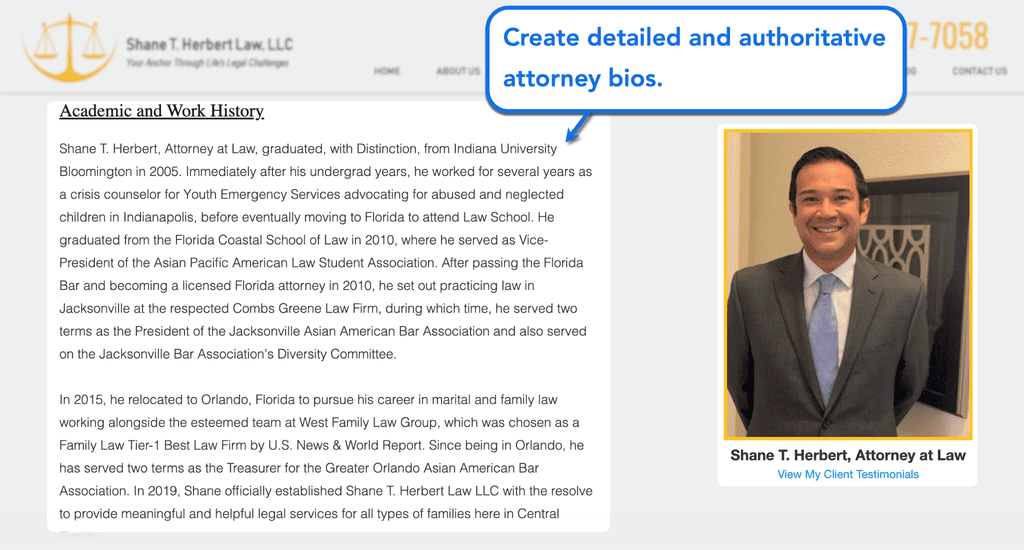
It’s also important to cite statutes, court decisions, or official sources for legal claims, while adding a visible “last reviewed” date. This helps establish strong activity, signaling that your firm keeps a close eye on the latest relevant updates in the legal space.
5. Use Structured Data That Matches the Page
Put simply, structured data is code that labels what a page is about and is designed specifically for crawlers.
Google keeps the rules simple: the markup has to match what’s visible on the page, and it should be validated.
Here’s a quick guide on the structured data types you should use and where:
| Type | Where It Goes | Worth Knowing |
| LegalService | The firm’s homepage/about page | Covers name, address, phone, office hours, and service areas. |
| Person | Attorney bios | Credentials (‘hasCredential’) and practice area topics (‘knowsAbout’) go here, and (‘worksFor’) ties the attorney back to the firm. |
| Review and AggregateRating | Reviews shown on the site | Mark up only what’s visible. |
| Attorney | Older sites only | On older law firm websites (marked as deprecated by Schema.org). The recommended alternative is ‘LegalService.’ |
Structured data and markups are best handled by your firm or agency’s developer. Regardless, run a test on the Schema Markup Validator tool to ensure your markups work as intended.
Creating Content AI Systems Can Cite
- Answer the question first, then explain. Someone contending with filing deadlines and other time-sensitive issues shouldn’t be asked to wade through several paragraphs to find answers.
- Back up legal claims with reputable sources. A statute, a court decision, an authoritative source, not just an assertion.
- State the jurisdiction and date plainly. Law varies by state and changes over time, so be sure both details are obvious (not just implied).
- Add original attorney commentary, interpretation, or practical content where appropriate. Offer genuine legal takes on rulings and other relevant changes or events from the lens of a practicing attorney.
- Make important facts easy to find. Be sure facts are easy to find and extract without stripping away necessary legal context.
Make Sure AI Search Bots Can Access Your Site
Being crawlable takes more than one setting.
A CDN or firewall rule can quietly override what robots.txt allows, so it’s worth checking both.
- Check robots.txt for the crawlers that actually matter. Make sure OAI-SearchBot, Claude-SearchBot, PerplexityBot, and other AI crawlers you prefer are allowed.
- Know the difference between a training bot and a search bot. Make sure you understand which bots are only used for LLM training and which are used to retrieve answers to user questions.
- Look at CDN and bot protection settings. Platforms like Cloudflare come with built-in AI bot controls, which can block crawlers at the edge before your robots.txt controls even fire.
- Deliberate utility of training vs. search crawlers. A lot of firms are comfortable blocking training crawlers while allowing search crawlers, but the access setup may vary from firm to firm (based on marketing priorities).
- Test specific pages (not just your homepage). Test your practice area pages, attorney bios, location pages, and other relevant site locations for crawlability issues.
Tools like Search Console can highlight pages that aren’t indexed and why. Use it to get ahead of potential crawlability issues that can affect your AI visibility.
Strengthening Your Law Firm’s Entity Signals
Consistent third-party references can reinforce information about the firm across search and AI systems.
A firm’s own website, its directory listings, and its social profiles should all align to strengthen the brand entity. Conflicting descriptions, on the other hand, do the opposite, and can create conflicting signals across search and AI systems.
- Match Name, Address, and Phone (NAP) details everywhere. Consistent NAP information an important local entity consistency signal. Make sure they read the same on your Google Business Profile, legal directories, bar association listings, and other profiles.
- Attach legal experiences to attorney bios. Make sure AI systems identify whose credentials, bar admissions, publications, and speaking engagements are on attorney bio pages. Mention associated practice areas and office locations for each attorney.
- Keep descriptions and other identifiers consistent. Keep core facts and market positioning on your firm consistent.
- Clean up what’s stale. An attorney who left your firm years ago or an old office address needs to be removed from your page. Leaving them on your website undermines the whole consistency that AI models and search engines look for.
Earning Mentions From Sources AI Systems Trust
The entity signals from earlier only work if other sources actually mention the firm somewhere. After all, an AI system checking for mentions across reputable sources needs those sources to exist first.
Just remember that not every mention has the same weight.
| Source Type | Examples | Why It Matters |
| Lega-specific listings | Avvo, Justia, FindLaw, and state bar profiles | Simple to claim while providing useful third-party corroboration of firm details. |
| Industry publications | Legal trade press and field-specific outlets (i.e., healthcare publications for med mal firms) | Signals real editorial review took place, something that plain legal directories can’t claim. |
| Government, court, and news sources | Local news coverage, court records, and government resources | Provides strong independent corroboration of information about your firm. |
| Academic sources | Cited articles, guest lectures, and research contributions | Only pulls weight in certain practices, as long as genuinely relevant. |
| Third-party interviews and commentary | Podcast appearances, quoted expert commentary, and panel discussions | Shows independent outlets that sought out the firm’s perspective. |
| Professional organizations | State and local bar associations, specialty legal groups | Membership and active involvement highlight credibility and peer recognition. |
Monitoring Your Law Firm’s AI Visibility
Monitoring tools can help track visibility trends, but manual prompt checks, referral data, citations, and Search Console data can also be useful.
Start with a tool built specifically for cross-platform visibility tracking:
1. Local Glyph
Local Glyph can check your firm’s visibility across ChatGPT, Perplexity, Google Maps, and local search results for real inquiries that prospective clients actually make. It comes with robust visual reporting tools that surface must-know datasets, like sentiment analysis, share of voice, and AI citations.
2. Local Falcon
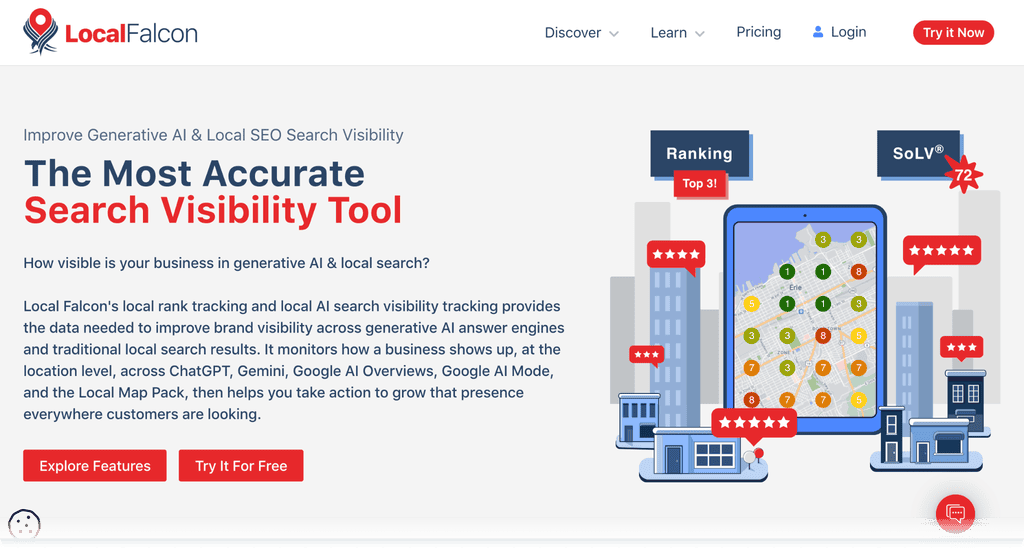
Local Falcon compiles visibility data by scanning geotargeted sources. It provides a bird’s-eye view of your local presence on organic search, AI tools, and snippets like the Google Local 3-Pack.
3. Yext
Yext is a brand visibility management platform that watches AI citations across specific locations and classifies them by source type, listings, owned websites, reviews, and third-party profiles. This helps firms see which kinds of sources AI systems are actually pulling information from.
Best Practices for Monitoring AI Visibility
- Run the same prompts on a schedule, not just once. AI answers shift over time, and a single check only captures a single snapshot.
- Phrase test prompts the way a real prospect actually would.
- Check for accuracy, not just presence. Outdated hours, wrong addresses, and other inaccurate statements must be addressed sooner rather than later.
- Watch competitors on the same prompts to identify gaps.
- Trace findings back to the entity and content strategies mentioned above.
- Put someone in charge of regularly monitoring AI visibility.
Staying Ahead as AI Transforms Search
AI search is transforming information discovery as we know it.
It takes ongoing attention to stay ahead of the pack and maintain visibility as search behaviors change. A firm that shows up clearly, gets cited accurately, and maintains solid entity signals while also tracking traditional organic search performance can definitely get ahead.
Our team at LaGrande Marketing helps law firms adapt their online presence as search behavior evolves. Schedule a free consultation here and let’s talk.
Related Post
-

ChatGPT Visibility for Law Firms
Potential clients are now going beyond traditional search results to find legal help. More and more are turning to AI tools like ChatGPT and Gemini,… -
How to Use ChatGPT to Supercharge Your Legal Practice
ChatGPT is one of the breakthrough technologies in recent years. With more and more lawyers integrating AI into their workflows, any law firm should look…